If your team uses Playwright, you probably have a suite that opens your site in real browsers, clicks through the important flows and fails the build when something breaks. That's a good place to be. It catches regressions before customers do, and it runs every time you ship.
But be precise about what a passing suite proves. It proves that the application behaved as expected, in the environment you tested, at the moment you tested it. For a typical pre-release suite, it is a release-time statement.
Your customers don't use your website only at release time. They use it at 2 a.m. on a Sunday, after a tag manager update, a CDN configuration change and a certificate renewal you never saw. The code may be identical to what passed your tests, but the conditions under which it runs have changed.
Your tests are built to ignore some of the things that break production
Playwright's own best-practice guide is clear on this point: "Only test what you control." It tells teams not to test external sites or third-party servers they don't control, and good test suites follow that advice. They mock third-party calls, stub slow dependencies and isolate the application under test so failures are deterministic.
That is the right way to design tests. A failing third-party service shouldn't make every build fail, and a slow external dependency shouldn't make your regression suite unpredictable. But there's an important consequence: some of the dependencies you've deliberately excluded from testing are still essential to the experience your customers receive.
A passing test may tell you little about:
- third-party scripts, tags and widgets loaded at runtime
- the CDN and edge configuration in front of your site
- the back-end APIs your pages call once they're live
- scripts, styles and other sub-resources that fail to load in production
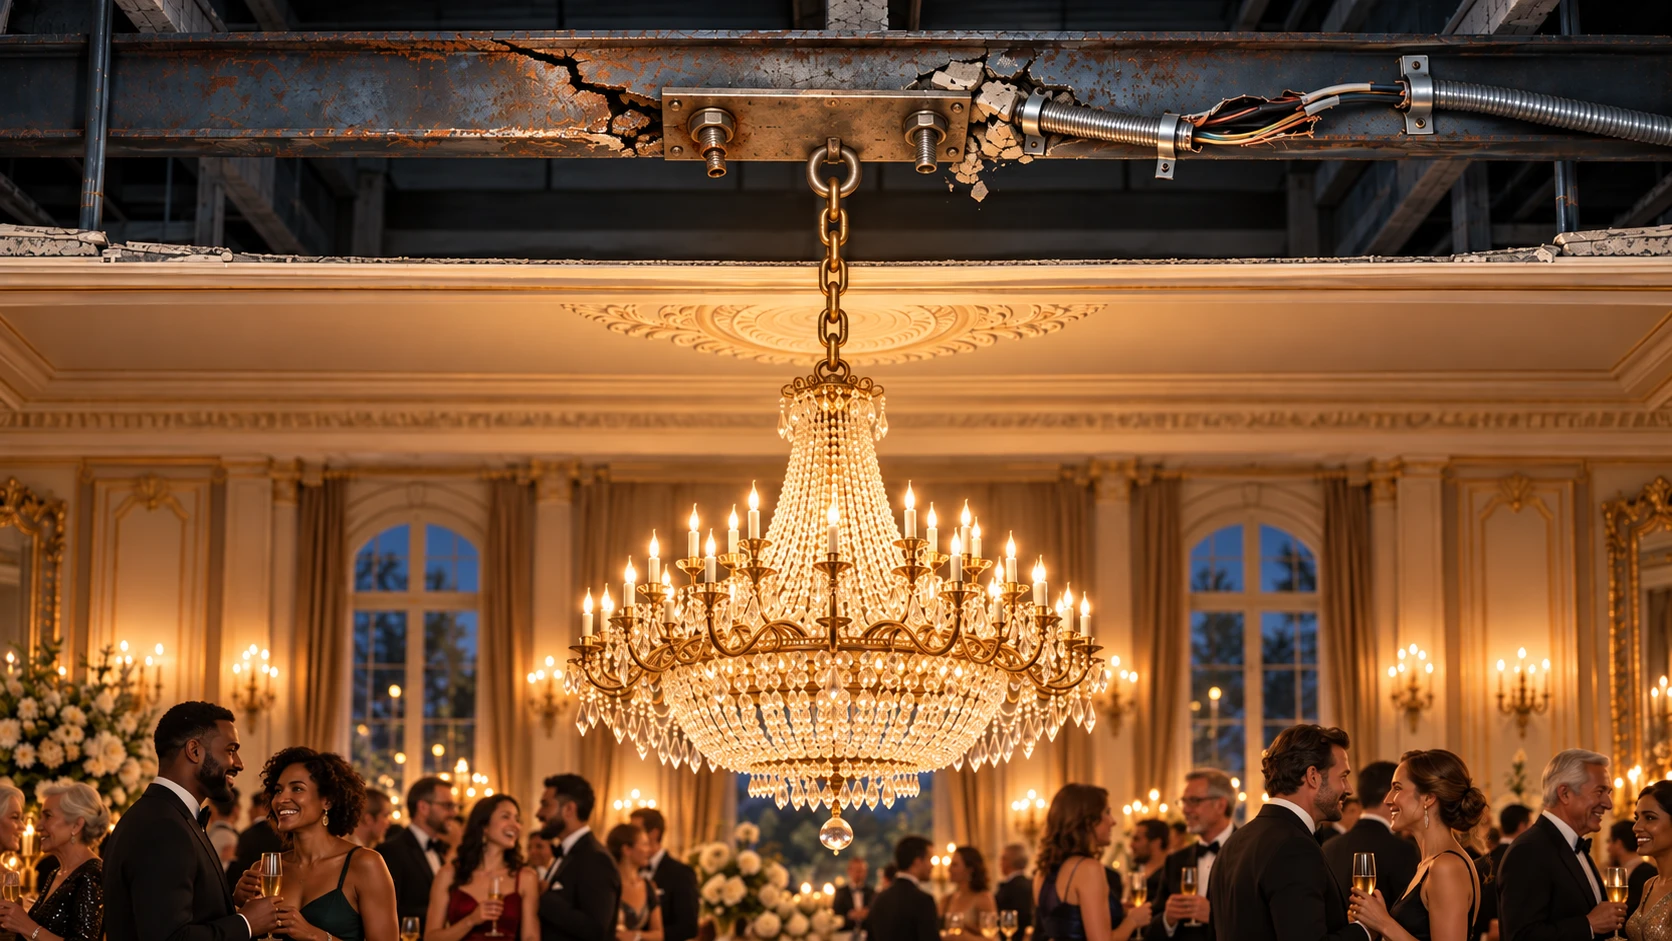
When one of those breaks, the server can still return 200 OK. The page can still be blank, half-rendered or throwing JavaScript errors for every visitor. A login form may appear but never become usable. A checkout page may load without the component needed to complete a purchase.
These are real production failures, even though the application code hasn't regressed and the server is responding correctly. The distinction isn't between good testing and bad testing. It's between controlling dependencies to establish whether your code works, and observing those dependencies to establish whether the delivered experience works.
Compare HTTP and browser results to find the gap
The most useful production signal isn't necessarily one more check. It's the difference between two kinds of check run against the same page.
An HTTP monitor asks the server a question and checks the answer. You define what you expect (status, headers, body content, size, latency) and you're told when the actual response differs.
A browser monitor loads the same page in a real browser and observes what happens after the response arrives: JavaScript execution, resource loading, rendering and page performance.
| HTTP monitor | Browser monitor | |
|---|---|---|
| What it runs | A plain HTTP request | A real headless browser loading the page |
| What it checks | Status, headers, body content, size and latency against what you expect | HTTP response and browser behavior, including console errors and failed resources |
| What it measures | Server response time | Rendering performance, including LCP, CLS, FCP and TTFB |
| What it can fail on | A response that differs from what you expect | Configured browser errors, resource failures or performance thresholds |
| Trade-off | Doesn't run JavaScript or render the page | Heavier, so it usually runs less often: every 15 to 60 minutes |
Each one is useful on its own. Together, they tell you where to look. Browser monitors can catch console errors and sub-resources that fail to load, which an HTTP monitor misses. An HTTP monitor can run more often and tells you whether the server is giving the right answer at all.
The distinction matters because a successful HTTP request and a successful page load aren't the same event. When the results disagree, that disagreement is itself useful information.
How to interpret signals that disagree
When you run both against the same page, the pattern of results can point you toward the layer at fault.
Imagine that an HTTP monitor reports a healthy checkout page, while the browser monitor begins detecting JavaScript errors and failed resources. The server hasn't necessarily failed. Something has changed between delivering the response and rendering a usable page. That gives the team a more specific place to begin investigating.
Other patterns are similarly useful:
- HTTP passes, browser fails. The server is answering as expected, so look at what happens after the response: a console error, a third-party script, a sub-resource that didn't load, or content that depends on JavaScript.
- HTTP fails. Start with the response path: the server, the network, the edge in front of it, or the check's own expectations. The browser result provides additional context.
- HTTP passes, but browser performance degrades. The page may still work, but the experience is worsening. Look at the render path, layout shifts and what loads before the main content.
- Both pass. The page is answering and rendering within the expectations you've configured, from the locations and at the times you've checked it. That's stronger production evidence than a passing pre-release suite alone.
These are starting points, not a diagnosis. A browser failure doesn't automatically identify the dependency responsible, and a passing check doesn't prove that every customer journey works. But the comparison helps turn "the site seems slow" or "the page isn't working" into a more specific question for a specific team.
Keep the suite. Add the production signal.
None of this replaces your Playwright suite. Tests and monitors answer different questions:
- Tests ask: did this release do what we built it to do?
- Monitors ask: is the website working for customers right now, including the parts we don't control?
You need both answers. Keep testing before release, then compare HTTP and browser results continuously after it.
The value of combining these signals isn't just broader coverage. It's an independent view of the application as it is delivered, rather than only as it was built. Your HTTP checks establish whether endpoints are returning the responses you expect. Browser checks add evidence about whether those responses produce a usable, correctly rendered page. Running them from external monitoring locations also exposes problems in the delivery path that may not appear inside your own infrastructure.
Pre-production pages need this too. A staging site or internal page usually isn't reachable from the public internet. Private nodes run browser checks from inside your own network, so you can monitor pages that aren't publicly accessible.
How to solve the disconnect
APIContext supports both monitor types, which can be run side-by-side for comparison and insights. When website monitors and API monitors both track the same endpoint or workflow, comparing the results becomes trivial, and alerts can be triggered off of multiple monitor failing criteria.
Get started
Browser monitoring is available on all paid plans. Start with a business-critical page, such as your login, checkout or customer portal, and add a browser monitor alongside the HTTP checks you already run. Comparing the two gives you a baseline for both response health and browser behavior, and a way to identify problems that either check alone might miss.
Contact support or your account team to turn it on. See how website monitoring works.